Category: Applied Mathematics

  • The Population Model That Fails—and Why Its Equation Is Everywhere: Population, Interest, and Radioactive Decay

    “`html

    A remarkably simple differential equation appears in many different places in the real world. We will begin with population growth. The first model we try will have a serious problem: it predicts unlimited growth. Fixing that problem will lead us to the logistic equation.

    Then, surprisingly, we will return to our original equation and discover that it was not a bad equation at all. The same equation describes continuous compound interest, radioactive decay, and many other processes.

    1. The Simplest Population Model

    Let P(t) denote a population at time t.

    One of the simplest assumptions we can make is this: the rate at which the population grows is proportional to the population itself.

    dP dt = kP, P(0) = P0.

    Here k>0 is a constant. The idea seems reasonable. If there are twice as many individuals, we might expect approximately twice as many births. A larger population therefore grows faster.

    The equation is separable:

    dPP = kdt.

    Integrating gives

    lnP = kt+C,

    and therefore

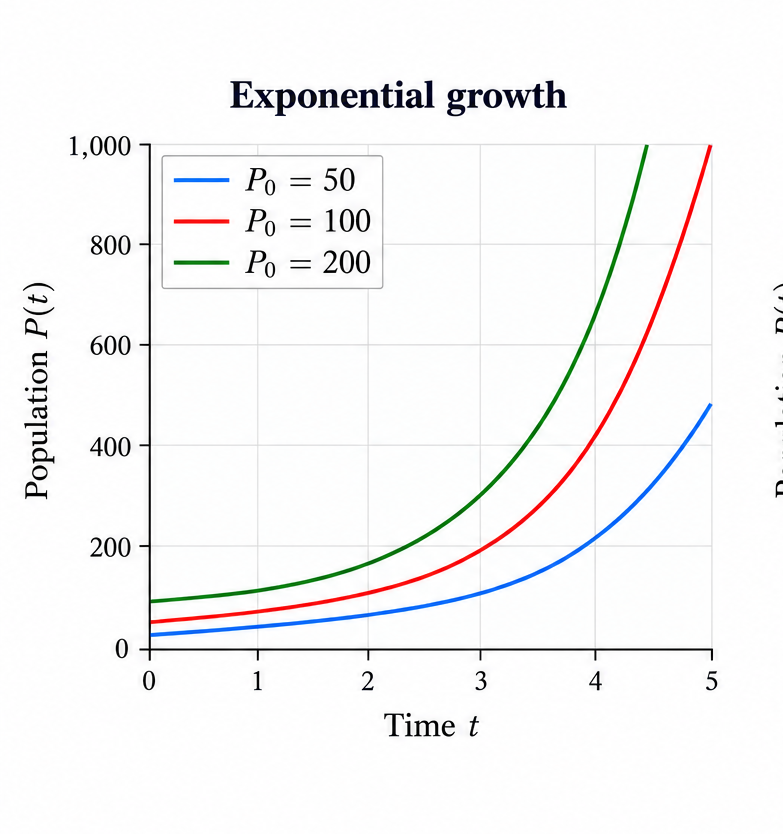
    P(t) = P0 ekt.

    This is exponential growth.

    There is an immediate problem. If k>0, then

    P(t) → ∞ as t→∞.

    According to this model, the population eventually becomes arbitrarily large. That cannot continue indefinitely in the real world. Food, water, space, and other resources are limited.

    So our first population model is useful for describing growth over some periods, but it cannot be the whole story.

    “`
    “`html

    2. Introducing a Carrying Capacity

    Suppose the environment can sustainably support a maximum population K. This number is called the carrying capacity.

    We modify our original equation to

    dP dt = kP ( 1 − P K )

    This is the logistic equation.

    The new factor

    ( 1 − P K )

    is what changes everything. When the population is small compared with K, this factor is close to 1, so the population behaves approximately like ordinary exponential growth. As the population becomes larger, the factor becomes smaller and the growth slows down.

    We Can Predict the Solutions Without Solving the Equation

    This is one of the most useful ideas in differential equations: we do not always need an explicit formula to understand what the solutions will do.

    First suppose

    0 < P < K.

    Then

    ( 1 − P K ) > 0,

    and consequently

    dP dt > 0.

    So the population increases.

    Now suppose P=K. Then

    ( 1 − P K ) = 0,

    so

    dP dt = 0.

    The population remains constant at the carrying capacity.

    Finally, if P>K, then

    ( 1 − P K ) < 0,

    and therefore

    dP dt < 0.

    The population decreases toward the carrying capacity.

    Where Is the Population Growing Fastest?

    The growth rate is

    kP ( 1 − P K ).

    As a function of P, this is a downward-opening quadratic:

    kP − kP2 K .

    Its maximum occurs at

    P = K 2 .

    This tells us something important about the shape of the population curve.

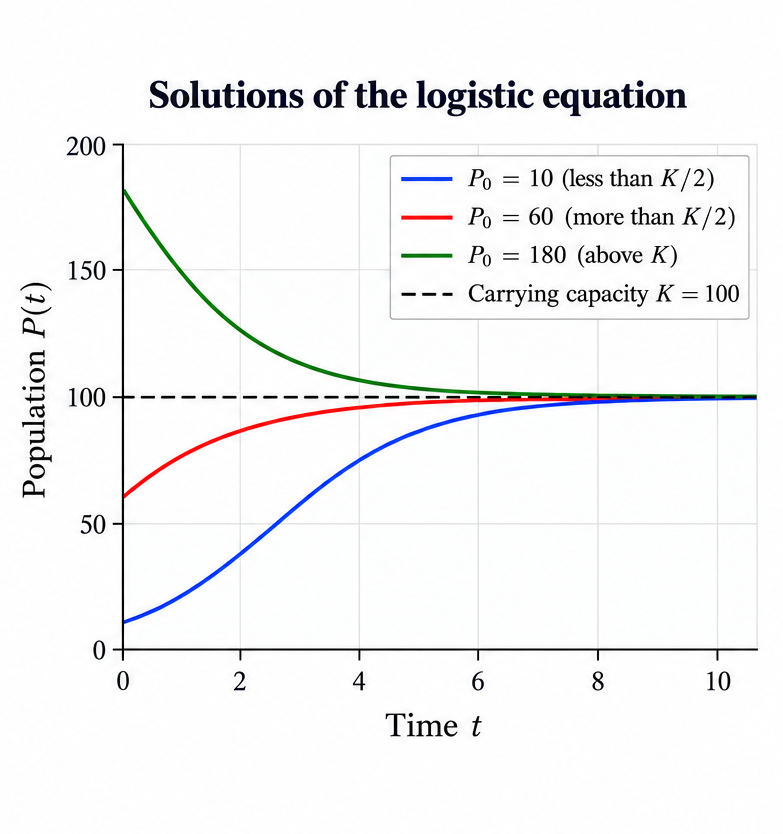
    If P0 < K2 , the population initially grows faster and faster. When it reaches P = K2 , its growth rate is greatest. After that, the population continues to increase, but more and more slowly as it approaches K. This produces the familiar S-shaped logistic curve.

    If K2 < P0 < K , the population begins above the point of fastest growth. It still increases toward K, but it slows down from the beginning.

    Finally, if P0 > K , the population decreases toward K.

    Thus, before solving the logistic equation, we can already predict the three different types of solution curves shown in the next figure.

    “`
    “`html id=”p87fcf”

    3. Now Let Us Solve the Logistic Equation

    We now return to the logistic equation

    dP dt = kP ( 1 − P K ), P(0) = P0.

    We have already learned a great deal about its solutions without solving it. Now let us find the actual formula.

    First separate the variables:

    dP P ( 1 − P K ) = kdt.

    Since

    1 P ( 1 − P K ) = 1P + 1 K−P ,

    we can integrate:

    ∫ ( 1P + 1 K−P ) dP = ∫ kdt.

    This gives

    lnP − ln ( K−P ) = kt + C.

    Combining the logarithms,

    ln ( P K−P ) = kt + C.

    Exponentiating both sides gives

    P K−P = C e kt .

    Using the initial condition P(0) = P0 , we obtain

    C = P0 K − P0 .

    After solving for P, we obtain the logistic growth formula:

    P(t) = K 1 + K − P0 P0 e −kt .

    Now the formula confirms what we predicted from the differential equation. For positive initial populations, the population approaches the carrying capacity:

    P(t) → K as t→∞.

    So the carrying capacity is not merely a number inserted into the model. It becomes the long-term population predicted by the model.

    4. Was Our Original Equation Really So Bad?

    We rejected the equation

    dy dt = ky

    as a model of population growth over an unlimited period of time. But the equation itself is one of the most important differential equations in mathematics.

    The initial-value problem

    dy dt = ky, y(0) = y0

    has the solution

    y(t) = y0 e kt .

    What changes from one application to another is the meaning of y and the sign and meaning of the proportionality constant.

    5. Continuous Compound Interest

    Suppose an amount of money A(t) earns interest continuously at an annual rate r. The rate at which the account balance changes is proportional to the amount currently in the account:

    dA dt = rA, A(0) = A0.

    Therefore,

    A(t) = A0 e rt .

    The same equation that produced exponential population growth now describes the growth of money.

    6. Radioactive Decay

    Now consider a radioactive substance. The more radioactive nuclei that are present, the more nuclei are available to decay. Thus, the magnitude of the decay rate is proportional to the amount currently present.

    This time the quantity is decreasing, so we write

    dN dt = − λN, N(0) = N0,

    where λ>0 is the decay constant.

    The solution is

    N(t) = N0 e − λt .

    7. One Equation, Many Processes

    We began with perhaps the simplest population model imaginable: the rate of change of a population is proportional to the population itself.

    As a long-term population model, it failed. Unlimited exponential population growth is impossible in an environment with limited resources.

    Introducing a carrying capacity led naturally to the logistic equation. Even more importantly, we were able to predict the behavior of its solutions before solving the equation.

    But our original equation was far from useless. The same basic mathematical law appears in continuous compound interest and radioactive decay.

    The common idea is simple:

    The rate of change of a quantity is proportional to the amount of that quantity currently present.

    Population, money, and radioactive atoms seem like completely different things. Mathematically, however, they can obey the same law.

    That is one of the remarkable features of differential equations: the same mathematical equation can describe very different processes in the real world.


    Related: See another example where a simple mathematical model produces a surprising—and ultimately unrealistic—prediction: A Sliding Ladder: Is It Better to Slide or Jump? .
  • How Do You Fit a Cylinder to Thousands of Points in Real Time?

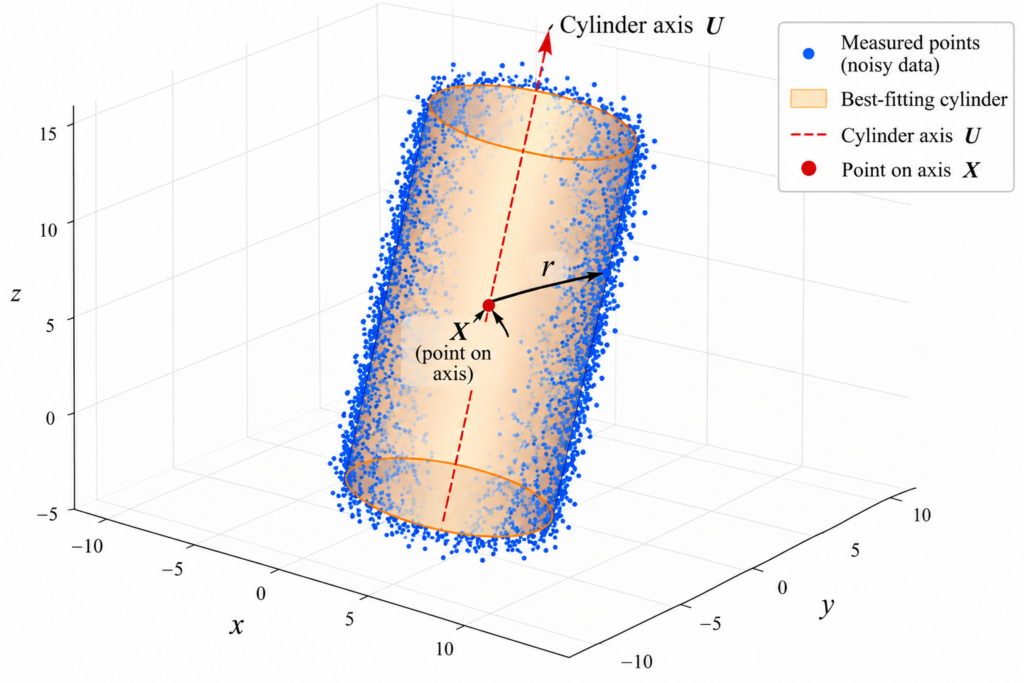
    Several years ago, I was given a practical geometry problem:

    Given thousands of measured points in three-dimensional space, find the cylinder that best fits them.

    There was an additional requirement that made the problem much more interesting. The calculation had to be fast enough to operate in real time.

    This meant that simply defining a mathematically reasonable fitting problem was not enough. The equations had to be arranged so that thousands of data points could be processed efficiently, the derivatives could be evaluated quickly, and each optimization step would require solving only a very small system of equations.

    The resulting method combines geometry, calculus, least squares, and the Gauss–Newton method.

    The Geometry of a Cylinder

    Suppose that

    X = ( x1 , x2 , x3 ) T

    is a point on the axis of a cylinder, and

    U = ( u1 , u2 , u3 ) T

    is a vector pointing along the axis.

    Let P be a point on the surface of the cylinder.

    The defining geometric property is simple:

    The perpendicular distance from every point on the cylinder to its axis is the radius r.

    Distance from a Point to the Axis

    Consider the vector

    P−X.

    Part of this vector points along the cylinder axis, while the remaining part is perpendicular to the axis.

    If α is the angle between P−X and U, then

    ‖P−X‖ sinα = r.

    Squaring gives

    ‖P−X‖ 2 sinα2 = r2.

    The dot product gives

    ( (P−X) T U ) 2 = ‖P−X‖ 2 ‖U‖ 2 cosα2 .

    Combining these relations eliminates the angle completely and gives

    ‖P−X‖ 2 − ( (P−X) T U ) 2 ‖U‖ 2 = r2 .

    This is the equation we need.

    The first term measures the squared distance from X to P. The fraction subtracts the squared component parallel to the axis. What remains is exactly the squared perpendicular distance to the axis.

    Turning the Geometry into a Residual

    Measured points will not lie exactly on a perfect cylinder.

    For a measured point P, define

    R(P) = ‖P−X‖ 2 − ( (P−X) T U ) 2 ‖U‖ 2 − r2 .

    For a point exactly on the cylinder,

    R(P) =0.

    For a noisy measured point, the residual will usually be nonzero.

    Reducing the Number of Unknowns

    At first the cylinder appears to have seven parameters: three coordinates for a point on its axis, three coordinates for the axis direction, and the radius.

    But there is redundancy.

    Moving the reference point X along the axis does not change the cylinder. Also, multiplying U by a nonzero constant does not change its direction.

    Assuming the cylinder axis is not parallel to the ( x1 , x2 ) plane, choose

    X = ( x1 , x2 , 0 ) T , U = ( u1 , u2 , 1 ) T .

    Now the entire cylinder is described by only five unknown numbers:

    S = ( x1 , x2 , u1 , u2 , r ) T .

    Two numbers locate the axis, two determine its direction, and one gives the radius.

    From Geometry to Least Squares

    Suppose our measuring system produces m points:

    P1 , P2 , … , Pm .

    Each point produces a residual Rj .

    We find the best-fitting cylinder by minimizing

    f(S) = 12 ∑ j=1 m R j 2 .

    This is a nonlinear least-squares problem.

    Why the Derivatives Matter

    Because the calculation had to run quickly, I derived the residual derivatives analytically.

    For each measured point, we need derivatives with respect to the five unknown parameters:

    ∇R = ( ∂R ∂x1 , ∂R ∂x2 , ∂R ∂u1 , ∂R ∂u2 , ∂R ∂r ) .

    The formulas contain several repeated expressions. In an implementation, there is no reason to calculate the same quantity over and over.

    For example, define

    q = (p1 −x1) u1 + (p2 −x2) u2 + p3 u12 + u22 + 1 .

    Then several derivative formulas become much shorter and faster to evaluate.

    This may look like a minor algebraic simplification on paper. In a real-time numerical algorithm that evaluates the same expressions thousands of times, such simplifications matter.

    The Jacobian

    Collect all the residuals into the vector

    E = ( R1 , R2 , … , Rm ) T .

    The Jacobian J has one row for every measured point and one column for every unknown parameter.

    Therefore,

    J is an m×5 matrix.

    Gauss–Newton

    The least-squares objective can be written compactly as

    f = 12 ‖E‖ 2 .

    Its gradient is

    ∇f = JTE .

    Gauss–Newton approximates the Hessian by

    ∇2f ≈ JTJ .

    At each iteration, instead of solving the original nonlinear problem from scratch, we solve

    JT J G = − JT E .

    The vector G tells us how to change the current estimate of the cylinder.

    Why Thousands of Points Are Not as Bad as They Sound

    This is the computational feature that makes the method especially attractive.

    Suppose the measuring system gives us 10,000 points.

    Then J has 10,000 rows.

    But it still has only five columns.

    Therefore,

    JTJ

    is only a

    5×5

    matrix.

    And

    JTE

    contains only five numbers.

    So although every iteration uses information from thousands of measured points, the linear system that determines the next step has only five unknowns.

    That is a very useful structure for a real-time calculation.

    Do Not Always Take the Full Step

    A Gauss–Newton direction tells us which way to move, but taking the entire step is not always wise.

    Write the update as

    Sk+1 = Sk + ak Gk , 0 < ak ≤ 1 .

    The step length is chosen adaptively. Start with ak=1 and reduce it if necessary until the new point produces a sufficient decrease in the objective function.

    In practice, the full step can often be accepted, but the line search gives the algorithm additional protection when the current estimate is not yet close to the solution.

    When Do We Stop?

    At a minimum we expect

    ∇f = 0 .

    Numerically, we stop when

    ‖∇f‖ < ε ,

    where ε is a small tolerance.

    There is no benefit in demanding far more numerical precision than the data and the computer arithmetic can support. An unnecessarily small tolerance can even create numerical difficulties.

    Did It Work?

    Yes.

    This was not a numerical example invented after the fact. The cylinder fitting problem came from a real application, and the algorithm had to work fast enough for real-time use.

    The implementation worked extremely well.

    What I found especially satisfying was that the final algorithm was built from familiar mathematical ingredients:

    geometry  →  least squares  →  calculus  →  Gauss–Newton  →  real-time computation.

    The important part was arranging those ingredients in the right way.

    From Cylinders to Cones

    A cylinder has constant radius. Once this fitting method works, a natural question is:

    What happens if the radius changes as we move along the axis?

    That leads to a cone.

    The cone-fitting problem requires one additional parameter—the opening angle—and the derivatives become more complicated. But the central strategy remains the same:

    choose an efficient geometric residual  →  derive its Jacobian  →  form a nonlinear least-squares problem  →  solve it with Gauss–Newton.

    That will be the subject of the next post.

    The Larger Lesson

    There is an important distinction between solving a mathematical problem and solving it in a form that is useful in practice.

    With 10,000 measured points, the original problem sounds large. But the geometry allows the unknown cylinder to be represented by only five parameters. Gauss–Newton then converts each iteration into a small five-variable linear problem.

    This is one of the recurring ideas in applied mathematics:

    A good mathematical formulation can be as important as the algorithm itself.

    When the formulation is right, a problem involving thousands of three-dimensional measurements can become small enough to solve in real time.


    A Closely Related Fitting Problem

    Cylinder fitting is only one version of the real-time surface-fitting problem. A closely related challenge arises when the measured surface is a cone rather than a cylinder.

    The change in geometry leads to a different mathematical problem, but the objective is the same: use the structure of the surface to obtain an accurate fit quickly enough for practical real-time computation.

    Continue exploring: How Do You Fit a Cone to Thousands of Points in Real Time?

  • How Do You Fit a Cone to Thousands of Points in Real Time?

    Several years ago, I was given an applied mathematics problem that sounded simple at first:

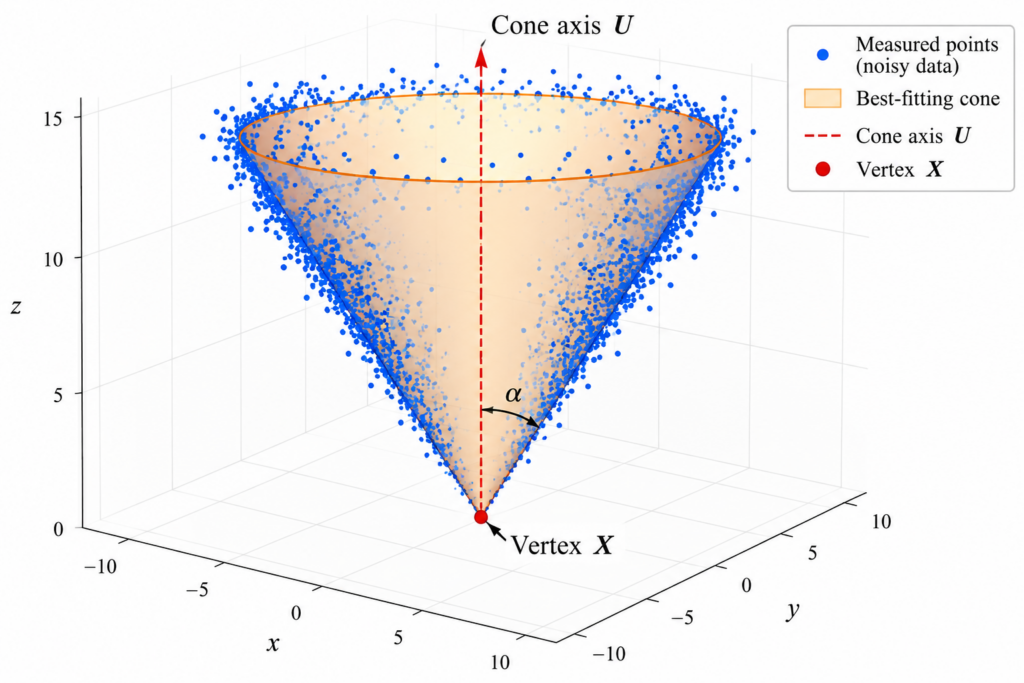
    Given thousands of measured points in three-dimensional space, find the cone that best fits them.

    But there was an additional requirement that changed the problem completely. The calculation had to be fast enough to be used in real time.

    It is one thing to describe an optimization problem mathematically. It is another thing to solve it repeatedly, quickly, and reliably while a real system is operating.

    The solution came from combining elementary geometry with nonlinear least squares and the Gauss–Newton method.

    The Geometric Problem

    Suppose a collection of measured points

    P1 , P2 , … , Pm

    lies close to the surface of an unknown right circular cone.

    We want to determine three things:

    the vertex of the cone, the direction of its axis, and its opening angle.

    Let

    X = ( x1 , x2 , x3 )

    be the vertex, let U point along the axis, and let α be the half-angle of the cone.

    If P lies exactly on the cone, then the vector

    P−X

    makes angle α with the cone axis.

    The dot-product formula for the angle between two vectors therefore gives

    ( (P−X) T U ) 2 = ‖P−X‖ 2 ‖U‖ 2 cosα2 .

    This one equation contains the geometry of the cone.

    Turning Geometry into an Error

    Measured data will not lie exactly on a perfect cone. There will be noise, measurement error, and small deviations from the ideal surface.

    So instead of asking whether a point satisfies the cone equation exactly, we measure how far it is from satisfying the equation.

    Define the residual

    R (P) = ‖P−X‖ 2 cosα 2 − ( (P−X) T U ) 2 ‖U‖ 2 .

    For a point exactly on the cone,

    R(P) =0.

    For a measured point near the cone, the residual will generally be nonzero.

    Why Use This Residual?

    There is an important practical point here.

    One could try to calculate the exact shortest geometric distance from every measured point to the cone. But when thousands of points must be processed repeatedly in real time, the computational form of the problem matters.

    The residual above is obtained directly from the cone equation. It can be evaluated using additions, multiplications, dot products, and a few simple functions.

    This was exactly what was needed for the application: a mathematical description that could be differentiated explicitly and evaluated rapidly.

    Six Unknown Parameters

    The direction of the axis does not depend on the length of U. Multiplying the axis vector by a nonzero constant gives the same axis.

    Assuming the axis is not parallel to the (x1, x2) plane, we can therefore write

    U = ( u1 , u2 , 1 ) .

    The entire cone is then described by only six unknown numbers:

    S = ( x1 , x2 , x3 , u1 , u2 , α ) T .

    Three numbers locate the vertex, two determine the axis direction, and one determines the cone angle.

    From One Point to Thousands of Points

    Suppose there are m measured points.

    For each point Pj , compute a residual Rj .

    We then look for the cone that minimizes the total squared residual:

    f(S) = 12 ∑ j=1 m R j 2 .

    This is a nonlinear least-squares problem.

    Why Not Just Solve the Equations?

    If the measurements were perfect, six carefully chosen points might appear to be enough to determine six unknown parameters.

    Real data do not work that way.

    Measurements contain noise, and a small collection of points may give a poor estimate. Instead, we can use hundreds or thousands of points simultaneously and find the cone that best fits all of them.

    But now the equations are nonlinear. There is no simple matrix formula that immediately gives the answer.

    This is where Gauss–Newton enters the story.

    The Jacobian

    Put all the residuals into one vector:

    E = ( R1 , R2 , … , Rm ) T .

    Then

    f = 12 ‖E‖ 2 .

    The Jacobian J contains the derivatives of every residual with respect to the six cone parameters.

    Its j-th row is

    Jj = ( ∂Rj ∂x1 , ∂Rj ∂x2 , ∂Rj ∂x3 , ∂Rj ∂u1 , ∂Rj ∂u2 , ∂Rj ∂α ) .

    In the actual implementation, these derivatives were derived analytically rather than estimated numerically.

    That requires more work at the beginning, but once the formulas are known, they can be evaluated very efficiently.

    The Key Gauss–Newton Approximation

    The gradient of the least-squares objective has a particularly simple form:

    ∇f = JT E .

    The exact Hessian is

    ∇2f = JTJ + ∑ j=1 m Rj ∇2 Rj .

    Computing the second term repeatedly is considerably more expensive.

    Gauss–Newton makes the approximation

    ∇2f ≈ JTJ .

    This approximation becomes especially natural when the fit is already good, because the residuals Rj are then small.

    That observation was crucial for a real-time implementation. Instead of constructing the complete second derivative at every iteration, we can work primarily with the Jacobian.

    One Iteration

    At the current estimate Sk , the Gauss–Newton direction Gk is obtained by solving

    JkT Jk Gk = − JkT Ek .

    Then update the six cone parameters:

    Sk+1 = Sk + ak Gk .

    Here 0<ak≤1 is the step length.

    Why Use a Line Search?

    Taking the full Gauss–Newton step is not always a good idea when the current estimate is still far from the solution.

    The implementation therefore reduces the step when necessary until the objective function decreases sufficiently.

    In mathematical form, choose the step length so that

    f ( Sk + ak Gk ) ≤ f (Sk) + ρ ak ∇fk T Gk .

    The purpose is simple: do not accept an iteration that moves too aggressively in a direction that fails to improve the fit sufficiently.

    The Real-Time Idea

    At first glance this may still look like a large calculation. There may be thousands of measured points.

    But notice something important.

    No matter how many data points we have, there are still only six unknown cone parameters.

    The Jacobian may have thousands of rows, but only six columns. The matrix

    JTJ

    is therefore only

    6×6.

    Similarly,

    JTE

    has only six components.

    So the data set can be large while the system that must be solved at each Gauss–Newton iteration remains very small.

    This is exactly the type of structure one wants to exploit in a real-time numerical algorithm.

    Did It Work?

    Yes.

    This was not an exercise invented to demonstrate Gauss–Newton. I developed the method because the cone-fitting calculation was needed in a real application, and it had to operate in real time.

    The implementation worked extremely well.

    That experience taught me an important lesson about applied mathematics: the best mathematical formulation is not necessarily the one that looks most sophisticated on paper.

    Sometimes the decisive question is:

    Can we formulate the problem so that the computer can solve it quickly enough to be useful?

    Why the Approximation Works

    There is another nice feature of Gauss–Newton.

    Recall that the exact Hessian is

    ∇2f = JTJ + ∑ j=1 m Rj ∇2 Rj .

    As the estimated cone approaches the data, the residuals become small. Consequently, the second term becomes less important and

    ∇2f ≈ JTJ .

    So as the algorithm approaches a good fit, the inexpensive approximation becomes increasingly appropriate.

    A Final Check

    Although computing the full Hessian at every iteration is expensive, it can still be useful after the optimization has finished.

    At the final solution we can evaluate

    ∇2f = JTJ + ∑ j=1 m Rj ∇2 Rj .

    If its eigenvalues are positive, the Hessian is positive definite and the computed stationary point is a local minimum.

    In other words, we use the inexpensive approximation while speed matters, and we can use the more expensive calculation afterward as a check.

    The Larger Lesson

    The mathematics of this problem can be summarized in one chain:

    3D measurements  →  cone geometry  →  residuals  →  least squares  →  Jacobian  →  Gauss–Newton  →  real-time fit.

    The cone itself is elementary geometry. Least squares is a classical idea. The derivatives require calculus. Gauss–Newton comes from numerical optimization.

    None of these ingredients alone solves the practical problem.

    The solution comes from putting them together in a form that a computer can evaluate rapidly.

    That is one of the most satisfying aspects of applied mathematics: sometimes a few familiar mathematical ideas, combined in the right way, turn a difficult real-world computation into something that works almost like magic.


    A Closely Related Fitting Problem

    Fitting a cone to a large cloud of measured points is one example of a broader problem: how can we recover a geometric surface accurately when the computation has to be fast enough for real-time use?

    A closely related problem replaces the cone by a cylinder. The geometry changes, but the same practical challenge remains: turn thousands of measurements into a reliable geometric fit without an expensive general-purpose optimization.

    Continue exploring: How Do You Fit a Cylinder to Thousands of Points in Real Time?

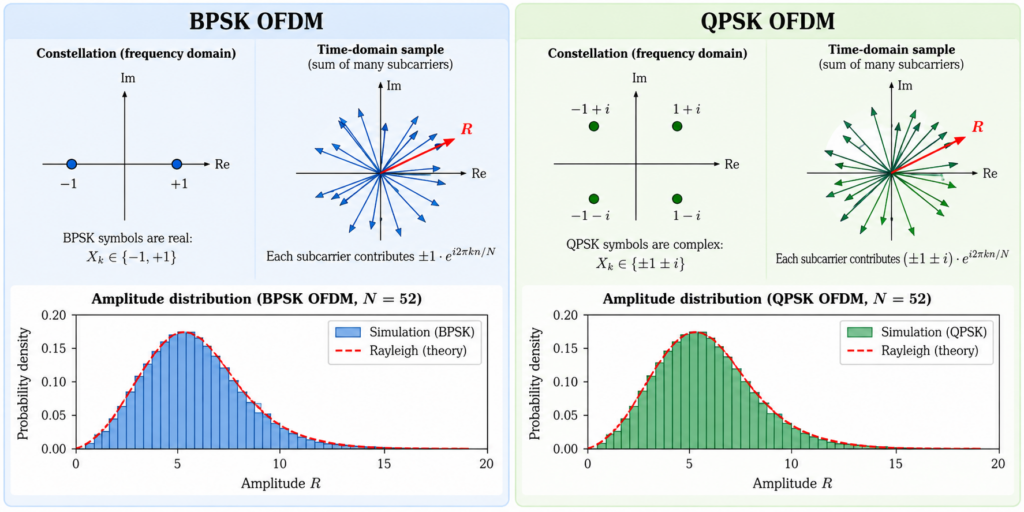
  • Why Does an OFDM Signal Have a Rayleigh Distribution?

    A complicated communication signal can sometimes be understood using surprisingly elementary mathematics.

    Consider a large number of vectors of length 1 pointing in random directions. Add them together. What can we say about the length of the resulting vector?

    This seemingly geometric probability problem leads directly to a standard mathematical model for OFDM (Orthogonal Frequency-Division Multiplexing), a technique used in modern digital communication.

    The path is beautiful:

    random phases → sine and cosine → Central Limit Theorem → two-dimensional Gaussian → Rayleigh distribution.

    Step 1: Add Random Unit Vectors

    Suppose that

    θ1 , θ2 , … , θN

    are independent random angles uniformly distributed between 0 and 2π .

    The corresponding unit complex numbers are

    e iθk = cos θk + i sin θk.

    Now add all of them:

    Z = ∑ k=1 N e iθk .

    Separating the real and imaginary parts gives

    Z = X + iY,

    where

    X = ∑ k=1 N cos θk , Y = ∑ k=1 N sin θk.

    Step 2: What Is the Distribution of One Coordinate?

    If θ is uniformly distributed on [0,2π] , then both sinθ and cosθ have density

    g (x) = 1 π 1−x2 , −1<x<1.

    This is sometimes called the arcsine distribution.

    By symmetry,

    E [cosθ] = E [sinθ] = 0.

    Also,

    E [ cosθ2 ] = E [ sinθ2 ] = 12.

    Therefore each coordinate has mean 0 and variance 12 .

    Step 3: The Central Limit Theorem Appears

    Now comes the key step.

    Both X and Y are sums of many independent random variables.

    When N is large, the Central Limit Theorem tells us that these sums are approximately normally distributed:

    X ≈ N ( 0 , N2 ) ,
    Y ≈ N ( 0 , N2 ) .

    In other words, the endpoint of our random walk is approximately described by a two-dimensional Gaussian distribution centered at the origin.

    Step 4: How Far Are We from the Origin?

    The amplitude of the complex sum is

    R = |Z| = X2 + Y2 .

    So we have reached a purely geometric question:

    If a point has two independent Gaussian coordinates, what is the distribution of its distance from the origin?

    The answer is the Rayleigh distribution.

    Since each coordinate has variance N2 , the approximate density of R is

    f (r) ≈ 2r N exp ( − r2 N ) , r≥0.

    This formula is important to interpret correctly. For a finite number of random unit vectors it is generally not the exact distribution. It is the large- N approximation produced by the Central Limit Theorem.

    A Shorter Derivation of the Rayleigh Formula

    There is also a beautiful geometric way to obtain the density.

    For large N, the joint density of (X,Y) is approximately

    p (x,y) = 1πN exp ( − x2 + y2 N ) .

    This density depends only on the distance from the origin.

    A thin circular ring of radius r and thickness dr has area approximately

    2πrdr.

    Multiplying the two-dimensional density by this ring area gives

    1πN exp ( − r2N ) · 2πrdr.

    Therefore,

    f (r) = 2rN exp ( − r2N ) .

    So the factor r in the Rayleigh distribution has a simple geometric origin: circles become longer as their radius increases.

    What Does This Have to Do with OFDM?

    An OFDM time-domain sample is produced by an inverse discrete Fourier transform. It therefore involves adding many complex contributions having different phases.

    This suggests viewing the sample, in a simplified model, as a sum of many complex vectors.

    That brings us back to exactly the random-vector problem above.

    An Example with 52 Active Carriers

    Consider a system with 64 available carrier positions, of which 52 are nonzero: 48 data carriers and 4 pilot carriers.

    The simple random-phasor model therefore suggests taking

    N=52.

    For a Rayleigh distribution with the density derived above, the expected amplitude is

    E[R] = πN 2 .

    For N=52 , this gives

    E[R] = 52π 2 ≈ 6.3907.

    How Good Is the Approximation?

    I originally investigated this question numerically by comparing the simple theoretical model with simulated OFDM signals.

    The theoretical mean amplitude for the 52-vector model is approximately 6.3907.

    A direct simulation of the random-vector model produced 6.3796.

    The corresponding simulated OFDM mean amplitudes were:

    Model Mean amplitude
    Rayleigh theory 6.3907
    Random-vector simulation 6.3796
    BPSK OFDM 6.3889
    QPSK OFDM 6.4015
    16QAM OFDM 6.4058
    64QAM OFDM 6.3837

    The agreement is remarkably good.

    A complicated digital communication signal has, at least at the level of its typical amplitude, been captured by a very simple model: add 52 vectors pointing in random directions.

    But What About Rare Peaks?

    Matching the average is not the whole story.

    For communication systems, unusually large signal peaks are important. An amplifier must be able to accommodate those peaks without severe distortion.

    This is where the difference between an approximation and an exact distribution becomes important.

    In the original numerical experiment, the simple theory tracked several OFDM simulations quite well at moderate thresholds. But differences appeared in the far tail of the distribution, particularly for BPSK.

    For example, at a peak-to-average threshold of 12 dB, the values from that simulation were approximately

    Model Tail probability
    Simple theory 4.0 × 10⁻⁶
    BPSK 1.969 × 10⁻³
    QPSK 9.4 × 10⁻⁵
    16QAM 7.9 × 10⁻⁵
    64QAM 4.0 × 10⁻⁵

    This illustrates an important lesson in probability.

    Two distributions can look very similar around their typical values while behaving quite differently in their extreme tails.

    The Central Limit Theorem explains the center of the distribution extremely well, but rare events can require more careful analysis.

    The Mathematics Behind a Communication Signal

    What I like about this example is the number of mathematical ideas that meet in one problem.

    We started with complex numbers:

    eiθ = cosθ + isinθ.

    Those became random vectors in the plane.

    Their coordinates led to probability distributions.

    Adding many of them brought in the Central Limit Theorem.

    The resulting two-dimensional Gaussian led, through elementary geometry, to the Rayleigh distribution:

    f (r) ≈ 2rN exp ( − r2N ) .

    And that simple formula gives a surprisingly accurate description of the amplitude of an OFDM signal.

    This is a good example of why mathematical modeling is so useful: the real system may be complicated, but sometimes the right simplified model exposes the mathematics underneath it.


    Where the Gaussian Function Enters the Story

    The Rayleigh distribution in OFDM is closely connected to Gaussian random variables. When many independent contributions combine, the in-phase and quadrature components of the signal are approximately Gaussian, and their magnitude produces the Rayleigh distribution.

    At the heart of the Gaussian distribution is the remarkable function e − x 2 . Its integral over the real line cannot be evaluated by finding an ordinary elementary antiderivative. Yet there is a beautiful way to compute it by moving from one dimension to two.

    Continue exploring: The Gaussian Integral and Beyond: From e^(-x²) to a Family of Integrals

  • How High Should the Compression Ratio of a Gasoline Engine Be?

    A gasoline engine becomes more efficient when its compression ratio is increased. So why not simply make the compression ratio as large as possible?

    There is a physical obstacle: increasing the compression ratio also increases the pressure inside the cylinder. An engine can withstand only a limited pressure.

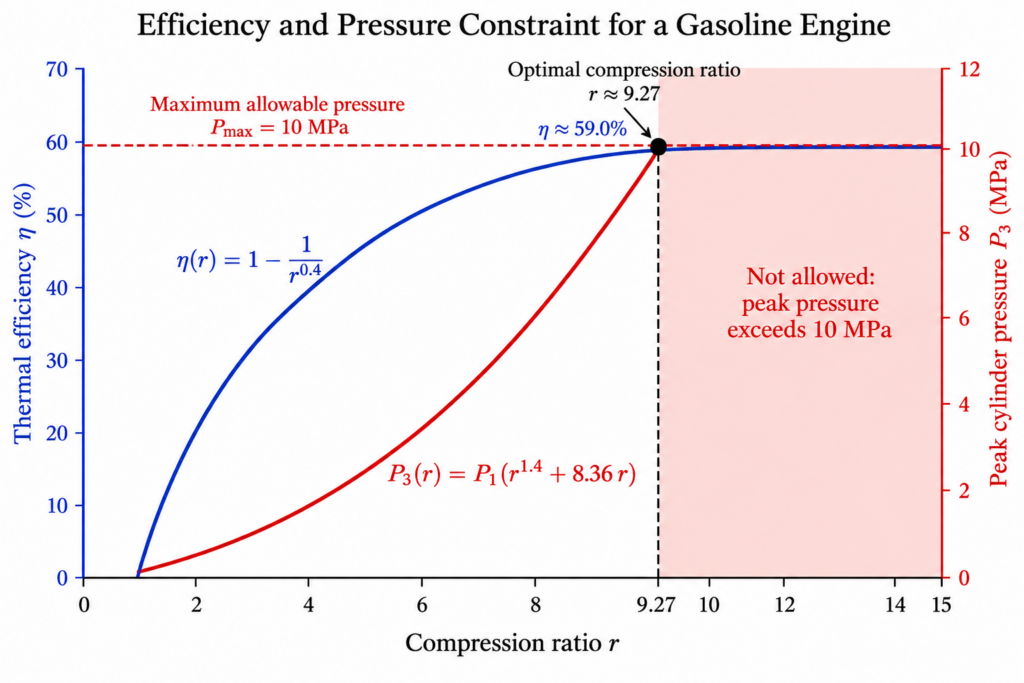
    This gives us a natural optimization problem:

    For a fixed amount of heat released during combustion and a fixed maximum allowable cylinder pressure, what compression ratio gives the greatest possible efficiency?

    The answer comes from combining a simple model of a gasoline engine with calculus.

    The ideal Otto cycle

    We use the ideal Otto cycle, the standard simplified model for a spark-ignition gasoline engine.

    Let

    r = V1 V2

    be the compression ratio, where V1 is the cylinder volume before compression and V2 is the volume after compression.

    Let P1 and T1 be the initial pressure and temperature.

    For an ideal gas undergoing adiabatic compression,

    T2 = T1 r γ−1

    and

    P2 = P1 rγ.

    Here

    γ = cp cv ,

    and for air we use the familiar approximation

    γ ≈ 1.4.

    Efficiency increases with compression

    The thermal efficiency of the ideal Otto cycle is

    η ( r ) = 1 − 1 r γ−1 .

    Differentiate:

    η′ ( r ) = ( γ − 1 ) r −γ .

    Since r>1 and γ>1, we have

    η′ ( r ) > 0.

    Thus, according to the ideal model, efficiency always increases as the compression ratio increases.

    So there is no unconstrained maximum. Mathematics would simply tell us to keep increasing r.

    A real engine, however, cannot withstand unlimited pressure. This is where the optimization problem becomes interesting.

    Adding a pressure constraint

    Suppose combustion adds a fixed amount of heat q per unit mass of air.

    In the ideal Otto model, heat is added at constant volume. Therefore,

    q = cv ( T3 − T2 ).

    Hence

    T3 = T2 + q cv .

    Because the volume does not change during combustion, the ideal-gas law gives

    P3 P2 = T3 T2 .

    Therefore,

    P3 = P2 ( 1 + q cv T2 ).

    Now substitute

    P2 = P1 rγ

    and

    T2 = T1 r γ−1 .

    We obtain

    P3 = P1 ( rγ + q cv T1 r ).

    The key equation

    Define

    B = q cv T1 .

    Then the maximum pressure reached during the idealized cycle is

    P3 = P1 ( rγ + Br ).

    Suppose the engine can safely withstand a maximum cylinder pressure Pmax. Then

    P3 ≤ Pmax.

    Define

    A = Pmax P1 .

    The pressure constraint becomes

    rγ + Br ≤ A.

    Where does the maximum occur?

    We already proved that the efficiency η(r) is increasing.

    Therefore, the most efficient engine uses the largest compression ratio permitted by the pressure constraint.

    The optimum must occur when the pressure reaches its allowable maximum:

    rγ + Br = A.

    This is an interesting kind of optimization problem. We do not find the optimum by solving η′ ( r ) = 0 . There is no critical point.

    Instead, calculus tells us that efficiency is increasing, and the physical constraint tells us where we must stop.

    A numerical example

    Take

    P1 = 100 kPa, T1 = 300 K.

    Use

    cv = 0.718 kJ/(kg K)

    and suppose combustion supplies

    q = 1800 kJ/kg.

    Then

    B = 1800 ( 0.718 ) ( 300 ) ≈ 8.36.

    Suppose the maximum allowable cylinder pressure is

    Pmax = 10 MPa = 10000 kPa.

    Therefore,

    A = 10000 100 = 100.

    Using γ=1.4, the optimal compression ratio satisfies

    r1.4 + 8.36r = 100.

    Solving this equation numerically gives

    r ≈ 9.27.

    Thus, in this simplified model, the greatest possible efficiency under the pressure restriction occurs at a compression ratio of approximately 9.27:1.

    What efficiency does this give?

    For γ=1.4, the ideal Otto-cycle efficiency is

    η = 1 − 1 r0.4 .

    Using r≈9.27,

    η ≈ 1 − 1 9.270.4 ≈ 0.590.

    So the theoretical efficiency is approximately

    η ≈ 59.0%.

    This is the efficiency of the idealized mathematical model, not the efficiency we should expect from a real gasoline engine. Real engines have friction, heat loss, pumping losses, finite combustion time, changing specific heats, and other effects that the ideal Otto cycle does not include.

    An unexpected seventh-degree polynomial

    There is one more mathematical surprise.

    We used

    γ = 1.4 = 75.

    Therefore the equation determining the optimal compression ratio has the form

    r 75 + Br = A.

    Let

    x = r 15 .

    Then

    r = x5

    and

    r 75 = x7.

    So our engine-design equation becomes

    x7 + B x5 − A = 0.

    For our numerical example,

    x7 + 8.36 x5 − 100 = 0.

    A practical question about the design of a gasoline engine has led us to a seventh-degree polynomial.

    We do not need to solve this polynomial symbolically. A numerical method gives the physically relevant positive root and therefore the optimal compression ratio.

    The mathematical lesson

    Without a pressure restriction, the ideal Otto model says

    larger compression ratio → greater efficiency.

    There is no finite optimum.

    But an engine has to withstand the pressure produced inside its cylinder. Once we impose the constraint

    P3 ≤ Pmax,

    the optimization problem has a finite solution.

    The optimum occurs precisely when increasing the compression ratio any further would violate the pressure constraint:

    P3 = Pmax.

    This illustrates an important idea in applied calculus: sometimes the optimum is not created by a critical point of the function—it is created by the constraint.

    Graph showing thermal efficiency and peak cylinder pressure versus compression ratio, with the optimal compression ratio of 9.27 determined by the 10 MPa pressure constraint.